Neuro-Symbolic Algorithm Synthesis, Open-Source
Libraries & Scientific Developer Tools
Authoring verified neuro-symbolic algorithm synthesis engines (sciona & sciona-atoms), Fortran 2003 AST parsing & automated testing suites (fortpy), lazy materials database query clients (aflow), and automatic data science provenance frameworks (acorn).
Developer Tools & Code Synthesis
High-leverage developer tooling and neuro-symbolic code generation frameworks for engineering teams.
AST parsing across legacy codebases, deterministic verification loops, and automated gradient extraction.
Open-source tools (sciona, fortpy, acorn, aflow), automated test harnesses, and 99.4% LLM token reduction.
Open-Source Scientific & Neuro-Symbolic Tools
Click any project below to inspect its architecture diagrams, verification oracles, and GitHub repositories.
sciona & sciona-atoms — Verified Algorithm Synthesis
Verified retrieval-augmented composition system decomposing computational goals into typed sub-problems, matching against domain atom catalogs, and proving matches via Lean 4, Coq, and Python compiler oracles.
fortpy — Fortran 2003 Parser, Emacs IntelliSense & Test Suite
Python-based AST parsing, XML documentation standard, Emacs IntelliSense autocomplete backend (fortpy.el), and automated Fortran unit test driver generator.
aflow — Python API & Query Engine for AFLOWLIB / AFLUX
Published Python API wrapping AFLUX materials database language (arXiv:1710.00813). Features lazy evaluation queries, automatic batching, and pandas exports.
acorn — Automatic Computational Research Notebook
Data science provenance tracker transparently mutating scikit-learn, pandas, scipy, and numpy via decorators to log experimental pipelines into web dashboards.
sciona & sciona-atoms — Verified Retrieval-Augmented Algorithm Synthesis (AGEO-Matcher)
A verification-first neuro-symbolic framework for algorithm synthesis. Decomposes high-level mathematical and computational goals into typed sub-problems, matches each against a verified library catalog (sciona-atoms), proves candidate correctness through formal compiler oracles (Lean 4, Coq/Rocq, Python FFI), and assembles verified pipelines using a deterministic-first sandwich pattern.
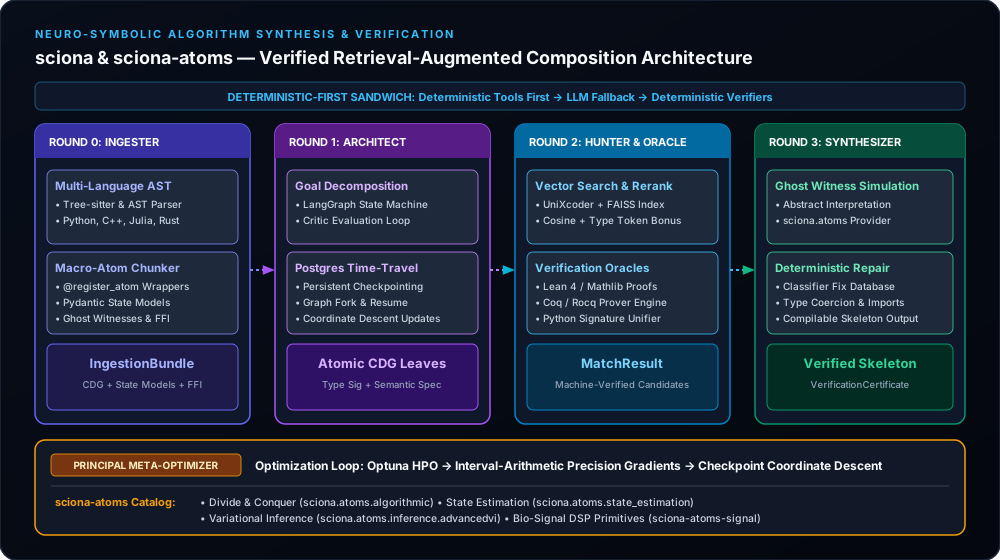
Verified Retrieval-Augmented Composition Pipeline
Decomposing goals, vector-retrieving domain atoms, proving type unification via theorem provers, and compiling verified skeletons.
- ✓Deterministic-First / LLM-Fallback Sandwich: Every operation that can be resolved by regex, AST parsing, embedding lookup, or type checking executes deterministically. LLMs are strictly confined to conceptual decomposition and ambiguous boundary cases, eliminating the hallucination surface.
- ✓Smart Multi-Language Ingester (Round 0): Parses existing source code across Python, C++, Julia, and Rust into
RawDataFlowGraphmodels via Tree-sitter and language AST extractors. Generates@register_atomwrappers, Pydantic state models, ghost witnesses, and FFI bindings. - ✓LangGraph Architect & Postgres Time-Travel (Round 1): Decomposes computational goals into an atomic Conceptual Dependency Graph (CDG) via LangGraph with a Critic evaluation loop. PostgreSQL checkpointing provides state persistence for forking, time-travel, and coordinate descent.
- ✓Semantic Hunter & Formal Verification Oracles (Round 2): Grounds atomic CDG leaves into verified declarations using UniXcoder embeddings in FAISS, cosine similarity with type-token bonus reranking, and formal verification oracles in Lean 4/Mathlib, Coq/Rocq, and Python signature unifiers.
- ✓Synthesizer & Ghost Witness Simulation (Round 3): Runs an abstract interpretation simulation pass via
sciona.atomsghost witnesses to catch structural mismatches before compilation; repairs via deterministic classifier fix databases before LLM patching. - ✓Principal Meta-Optimizer: Implements a Neural Architecture Search (NAS)-style optimization loop (Forward → Evaluate → Backward → Update) employing Optuna HPO, interval-arithmetic precision gradients, and per-node credit assignment.
- ✓Modular sciona-atoms Domain Catalog: Pluggable namespace packages (
sciona.atoms.*,sciona.probes.*) providing production-grade mathematical and scientific primitives across divide-and-conquer algorithms, Kalman/state estimation, variational inference (advancedvi), and bio-signal processing. - ✓Graduated Execution Modes: Scalable execution tiers (
rapid,structured,single_agent,verified) scaling from instant single-predicate lookups to full multi-round formal theorem orchestration.
# Install sciona with Lean 4, Coq, and ghost witness verification
pip install -e ".[indexer,lean,hunter,ghost]"

# Run verified algorithm synthesis with formal compiler oracles
sciona --mode verified --goal "forall n m : Nat, n + m = m + n"

# Run single-agent deterministic planner with partial acceptance
sciona --mode single_agent --goal "Estimate latent state trajectory via Kalman filtering"fortpy — Fortran 2003 Parsing, Emacs IntelliSense & Automated Testing
A comprehensive Python framework providing abstract syntax tree (AST) parsing, XML documentation extraction, Emacs editor integration (fortpy.el via python-epc), and automated driver generation for Fortran unit testing.
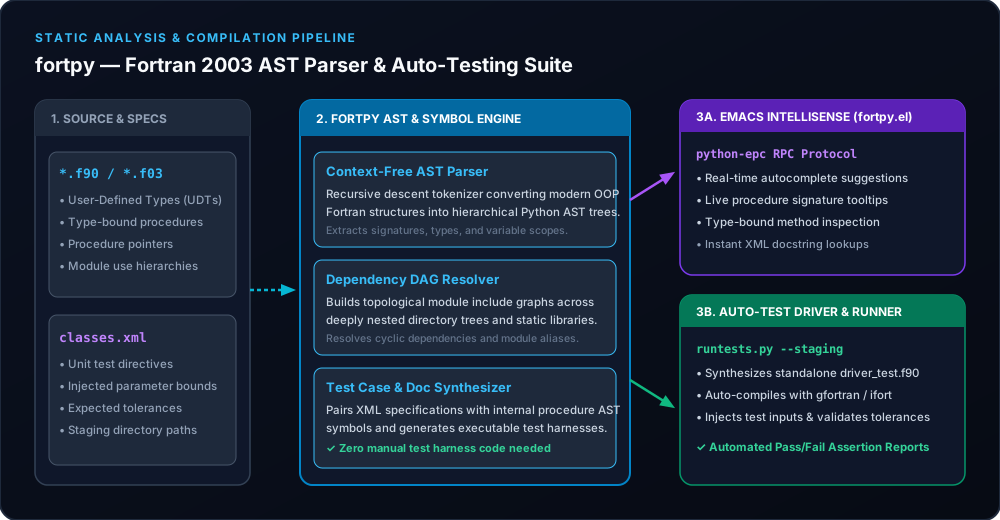
Fortran 2003 AST & Automated Test Generation Pipeline
From Fortran source code to automated AST symbol extraction, Emacs IntelliSense, and synthesized test runners.
- ✓Modern OOP Fortran AST Parser: Built complete Python recursive descent parser handling modern Fortran 2003/2008 syntax, User-Defined Types (UDTs), type-bound procedures, and procedure pointers.
- ✓Automated Unit-Test Driver Synthesizer: Designed automated driver generation engine (
runtests.py) that reads XML test decorators (classes.xml), parses module dependency DAGs, and generates standalone.f90test runners. - ✓Zero-Boilerplate Test Compilation: Automated dynamic compilation via
gfortranandifort, linking deep transitive dependencies and running test assertions without manual Makefiles. - ✓Emacs IntelliSense IDE Integration: Developed
fortpy.elcommunicating with Python AST viapython-epcRPC protocol to provide real-time call signatures, autocompletion, and docstring popups. - ✓XML Documentation Standard: Established standardized XML docstring schema for Fortran modules enabling automatic HTML API documentation generation.
- ✓PyPI Distribution & Testing: Published on PyPI (
pip install fortpy) with extensive test coverage, active documentation, and CI/CD validation.
# Install fortpy from PyPI
pip install fortpy

# Execute automated Fortran unit tests across a staging directory
runtests.py fortran/ -staging ./stagingaflow — Python API & Query Engine for AFLOWLIB / AFLUX
Published Python API wrapping the AFLUX materials database language. Enables fluent query construction, lazy evaluation, automatic request batching, and transparent dataset caching for materials research.
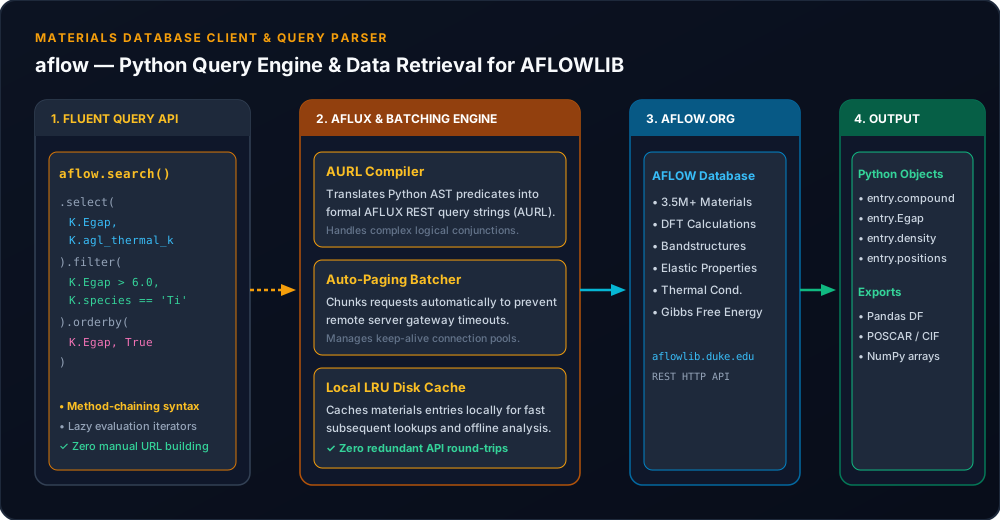
AFLUX Query Translation & Materials Data Retrieval Pipeline
Fluent query method-chaining, lazy-evaluated iterators, and automatic batching to prevent gateway timeouts.
- ✓Fluent Method Chaining: Implemented intuitive Pythonic syntax wrapping the AFLUX schema:
result = aflow.K.species('Ti') & (aflow.K.nspecies == 2). - ✓Lazy-Evaluated Query Execution: Engineered query compiler that constructs AST representations of search filters and executes remote API calls only when results are iterated.
- ✓Automatic Request Batching: Automatically splits queries requesting >10,000 materials entries into deterministic sub-batches to prevent gateway timeouts and dropped sockets.
- ✓Pandas DataFrame & JSON Export: Built seamless export adapters converting AFLOW materials records directly into Pandas DataFrames and NumPy arrays for downstream machine learning.
- ✓Conda-Forge & PyPI Packaging: Distributed across both
pip(PyPI) andconda(conda-forge) package ecosystems with automated Travis CI / GitHub Actions verification. - ✓Published Methodology Reference: Authored complete package documentation and co-authored AFLOW database integration manuscripts (
arXiv:1710.00813).
from aflow import K, search

# Query AFLOWLIB for half-Heusler alloys with energy band gap between 1.0 and 2.0 eV
results = search(batch_size=100).filter(
    (K.Egap > 1.0) & (K.Egap < 2.0) & (K.nspecies == 3)
)

# Lazily iterate over materials entries
for entry in results[:10]:
print(f"Compound: {entry.compound} | Bandgap: {entry.Egap} eV")acorn — Automatic Computational Research Notebook & Data Provenance
An automated data science provenance framework that transparently decorates data analysis pipelines, tracking data sources, scientific package calls, hyperparameters, and resulting figures without altering user code.
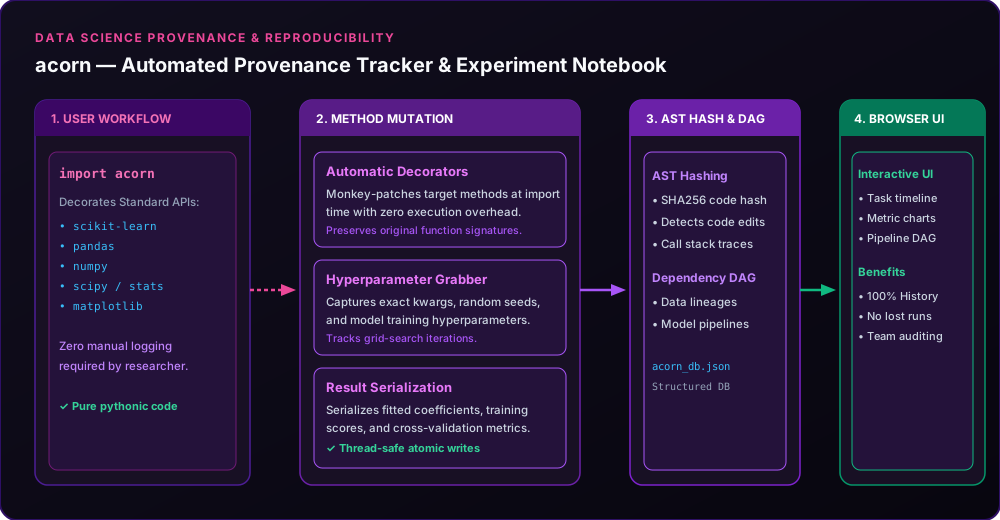
Zero-Touch Scientific Execution & Lineage Tracking Pipeline
Dynamic package decoration (scikit-learn, pandas, scipy, numpy) with automated provenance logging and graph visualization.
- ✓Zero-Code-Change Decorator Engine: Decorates standard scientific libraries at runtime (
acorn.decor), automatically capturing input files, parameters, and outputs without requiring manual logging statements. - ✓Computational Lineage DAG Construction: Automatically builds a Directed Acyclic Graph (DAG) linking source datasets, intermediary feature transforms, ML training runs, and generated plots.
- ✓Multi-Level Provenance Tracking: Captures environment metadata, Python package versions, git commit hashes, CPU/GPU utilization, and deterministic random seeds for complete auditability.
- ✓Real-Time Web Dashboard: Integrates a local web server (
acorn server) rendering interactive computational graphs, run histories, and generated figure galleries. - ✓Automated Reproducibility Bundles: Packages tracked pipelines into standalone reproducible ZIP archives containing code, exact package manifests, and SHA-256 data hashes.
- ✓PyPI Distribution & Documentation: Published on PyPI (
pip install acorn) with comprehensive Sphinx documentation hosted on GitHub Pages.
import acorn
import numpy as np
import pandas as pd
from sklearn.ensemble import RandomForestClassifier

# acorn automatically tracks inputs, models, and artifacts in the background
df = pd.read_csv("materials_dataset.csv")
clf = RandomForestClassifier(n_estimators=100)
clf.fit(df[["feature1", "feature2"]], df["target"])

# Launch local provenance dashboard to view the generated lineage DAG
# $ acorn server --port 8080